Transformers & Self-Attention: Simple Complete Guide
Understand Transformers and Self-Attention without heavy math. Learn how models process words in parallel, how Query, Key, and Value work, and why Transformers power modern LLMs.
Kulbhushan PukaleUnderstand Transformers and Self-Attention without heavy math. Learn how models process words in parallel, how Query, Key, and Value work, and why Transformers power modern LLMs.
Kulbhushan PukaleMaster sequential neural networks. Learn how Recurrent Neural Networks process time-series and text, why vanishing gradients crippled early…
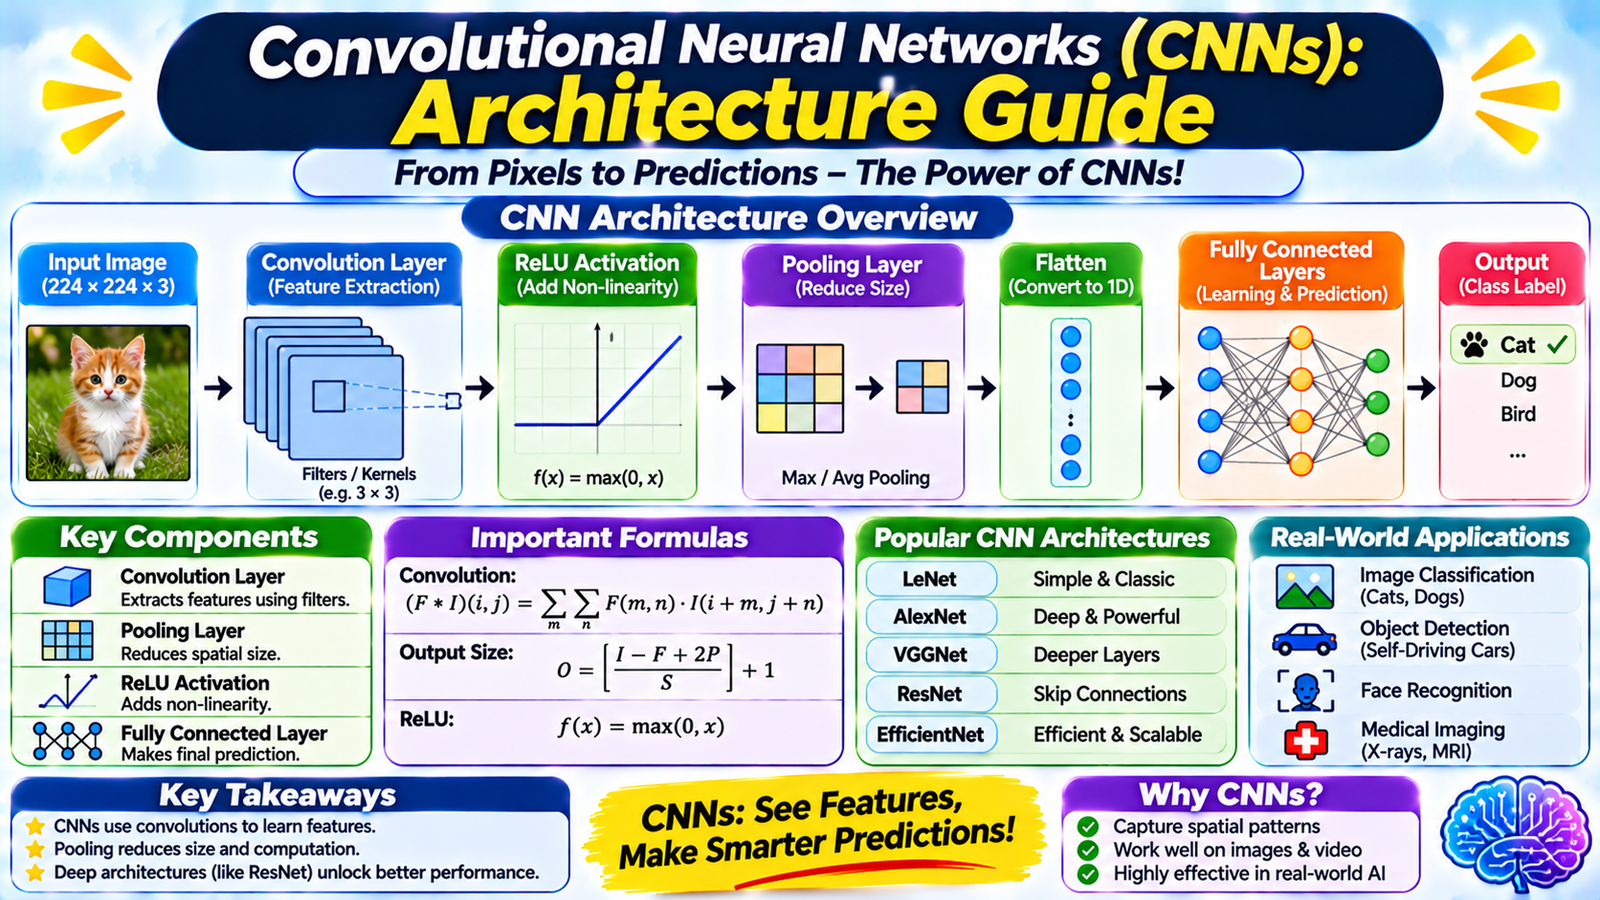
Kulbhushan PukaleUnderstand how Convolutional Neural Networks see the world. Explore convolution kernels, stride, padding, pooling layers, receptive fields…
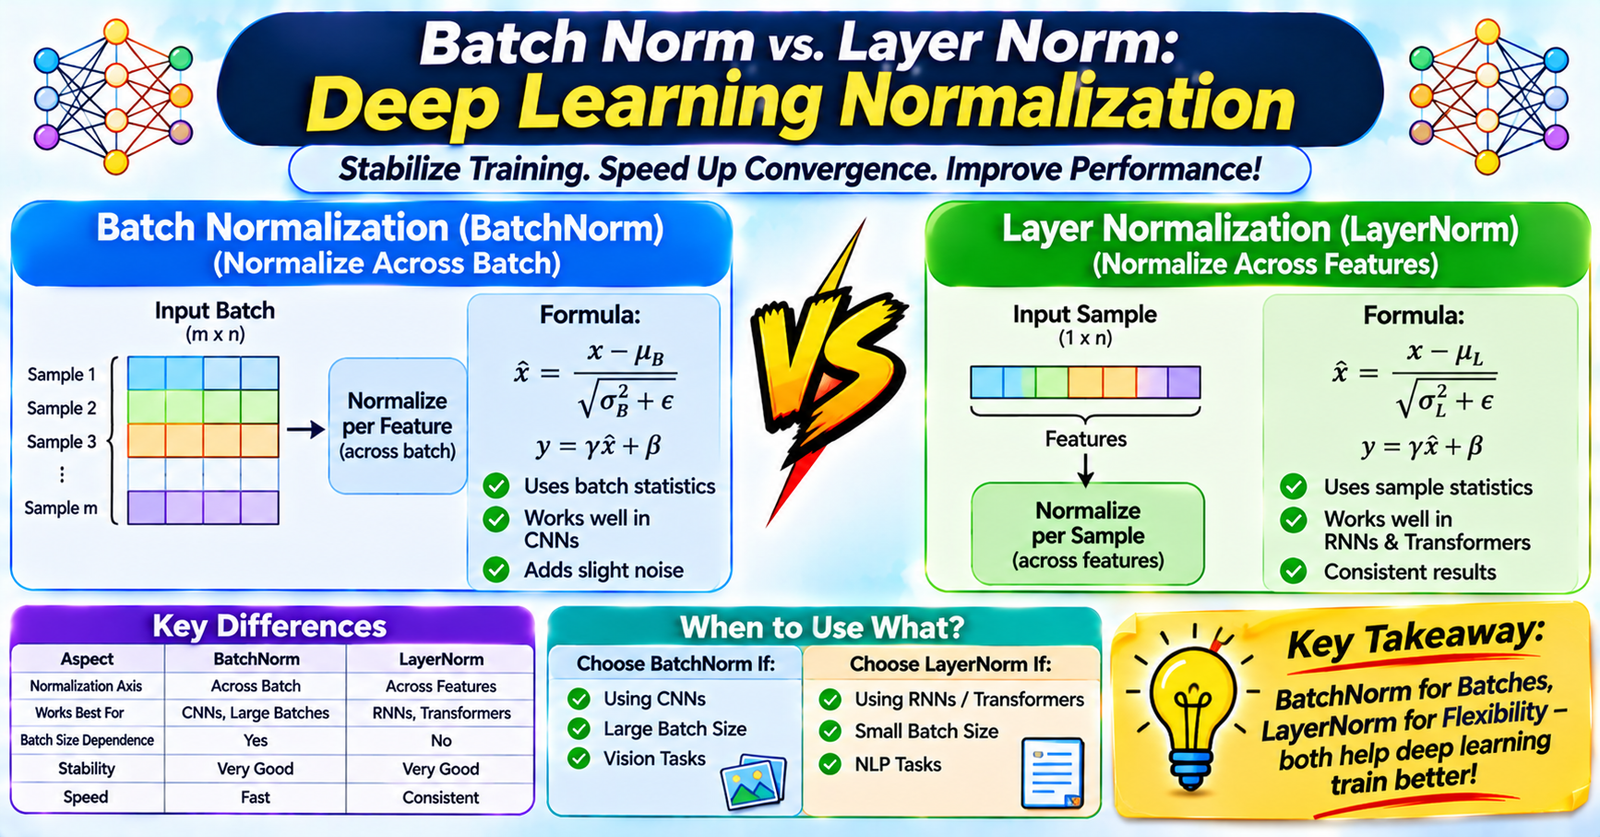
Kulbhushan PukaleCompare Batch Normalization and Layer Normalization. Learn the mathematical differences across tensor axes, why CNNs rely on BatchNorm, and…
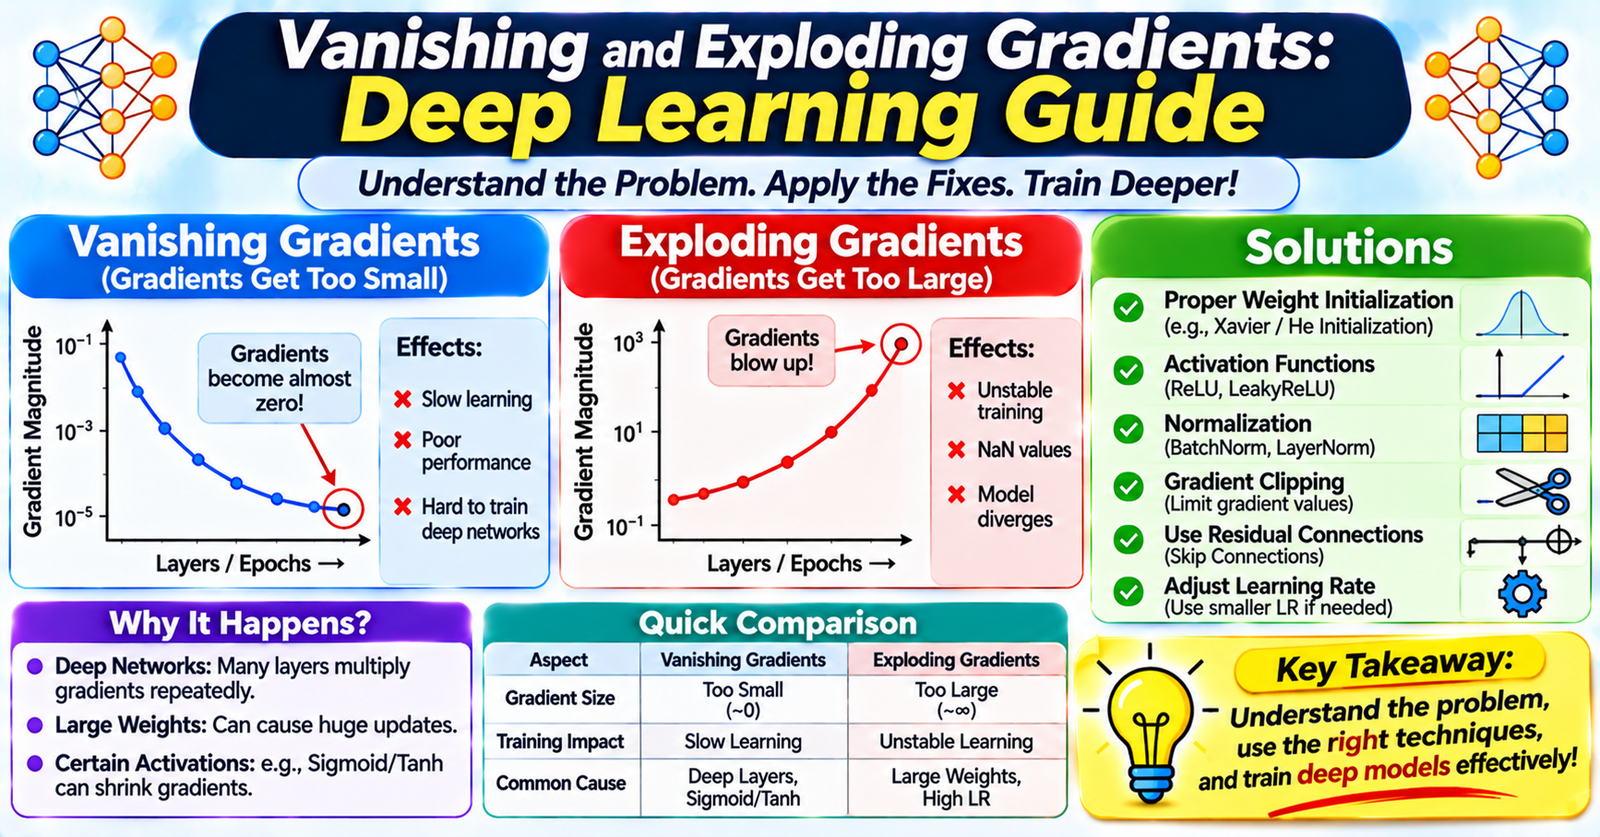
Kulbhushan PukaleUnderstand why deep neural networks fail to train due to vanishing and exploding gradients. Explore backpropagation chain rule math, activat…
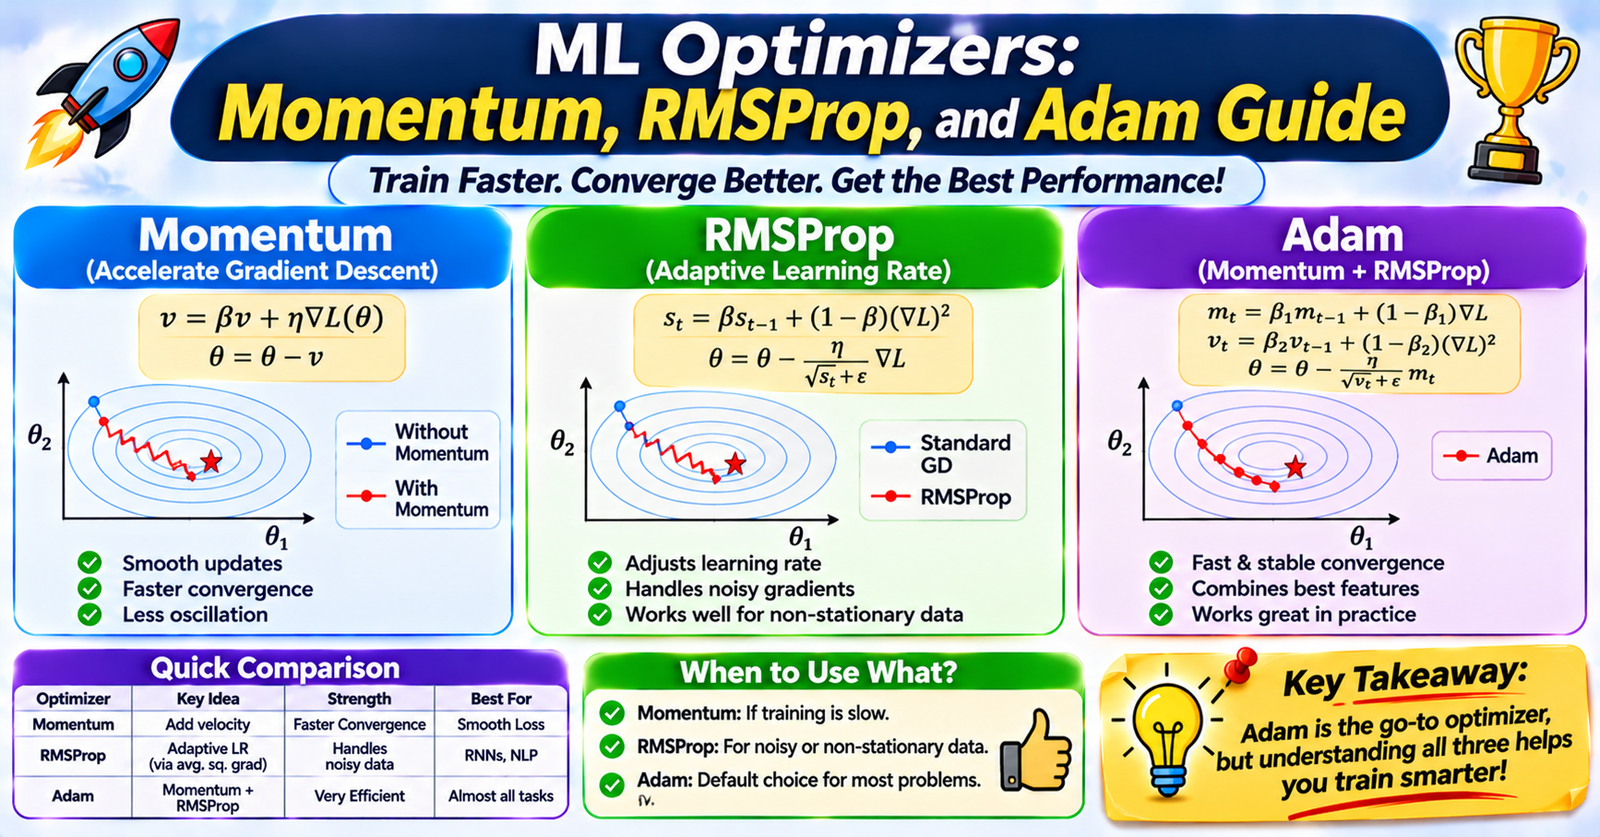
Kulbhushan PukaleDiscover how neural networks navigate loss landscapes. Compare Momentum, RMSProp, and Adam, learn first and second moment math, and select t…
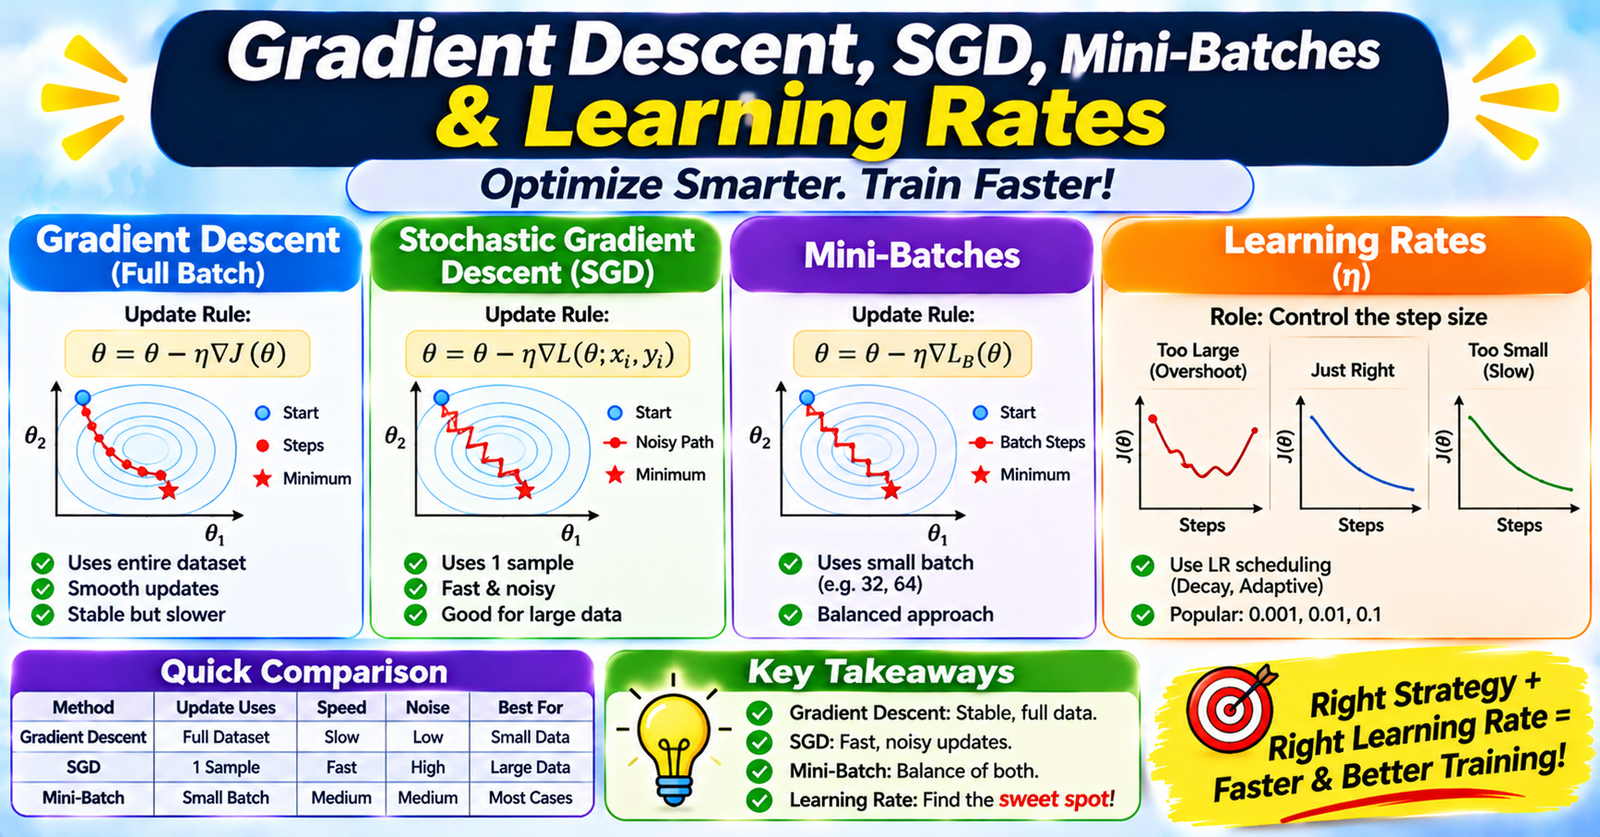
Kulbhushan PukaleDemystify ML optimization. Compare Batch Gradient Descent, Stochastic Gradient Descent (SGD), and Mini-Batch SGD. Learn learning rate dynami…
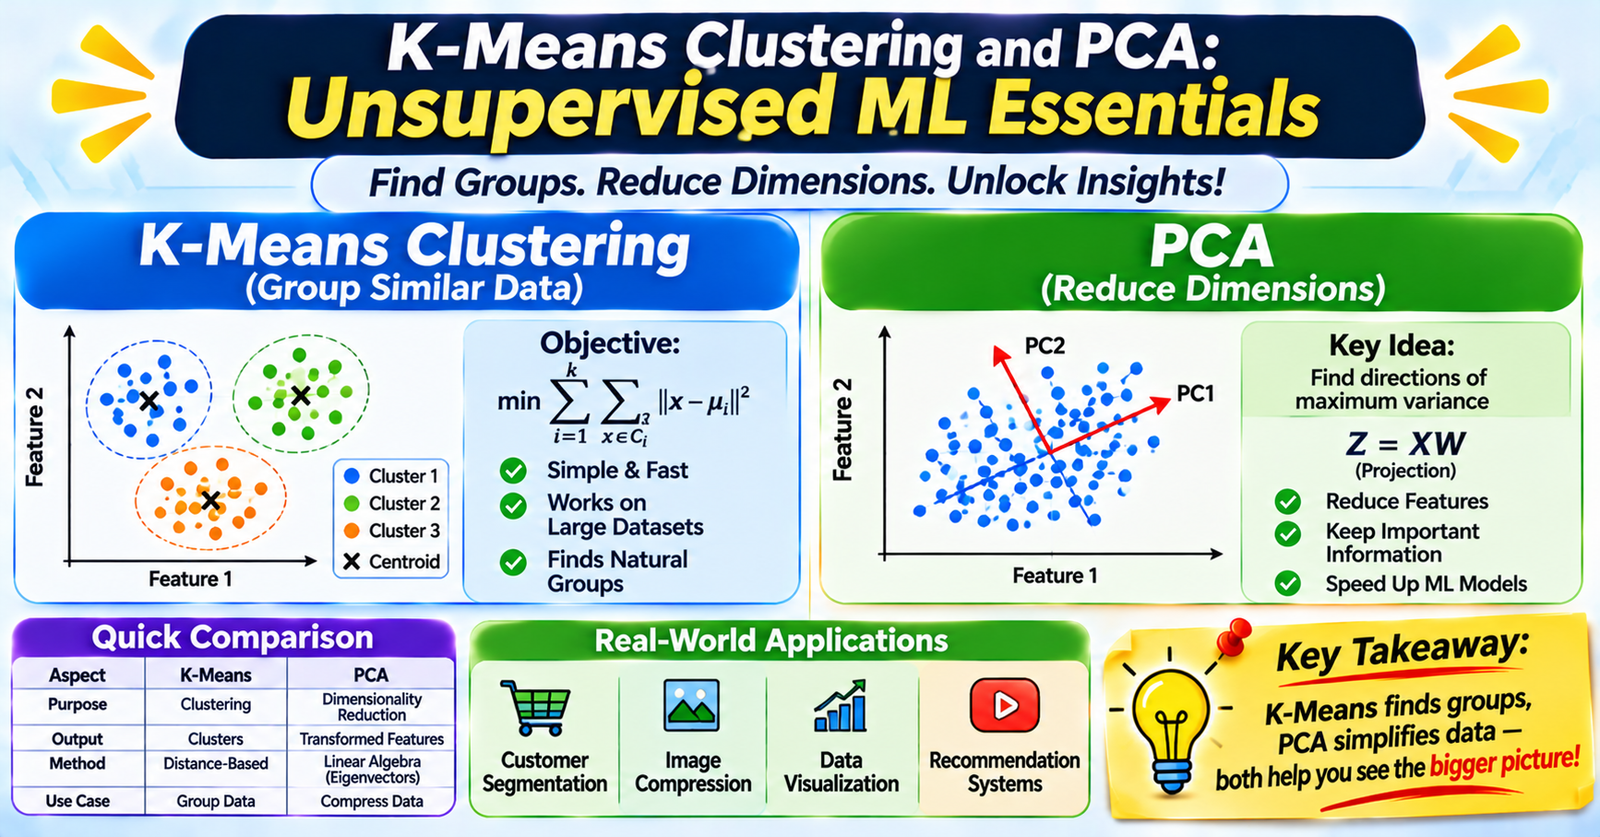
Kulbhushan PukaleUncover patterns in unlabelled data. Learn how K-Means partitions feature spaces, how PCA compresses high-dimensional vectors, and how to co…
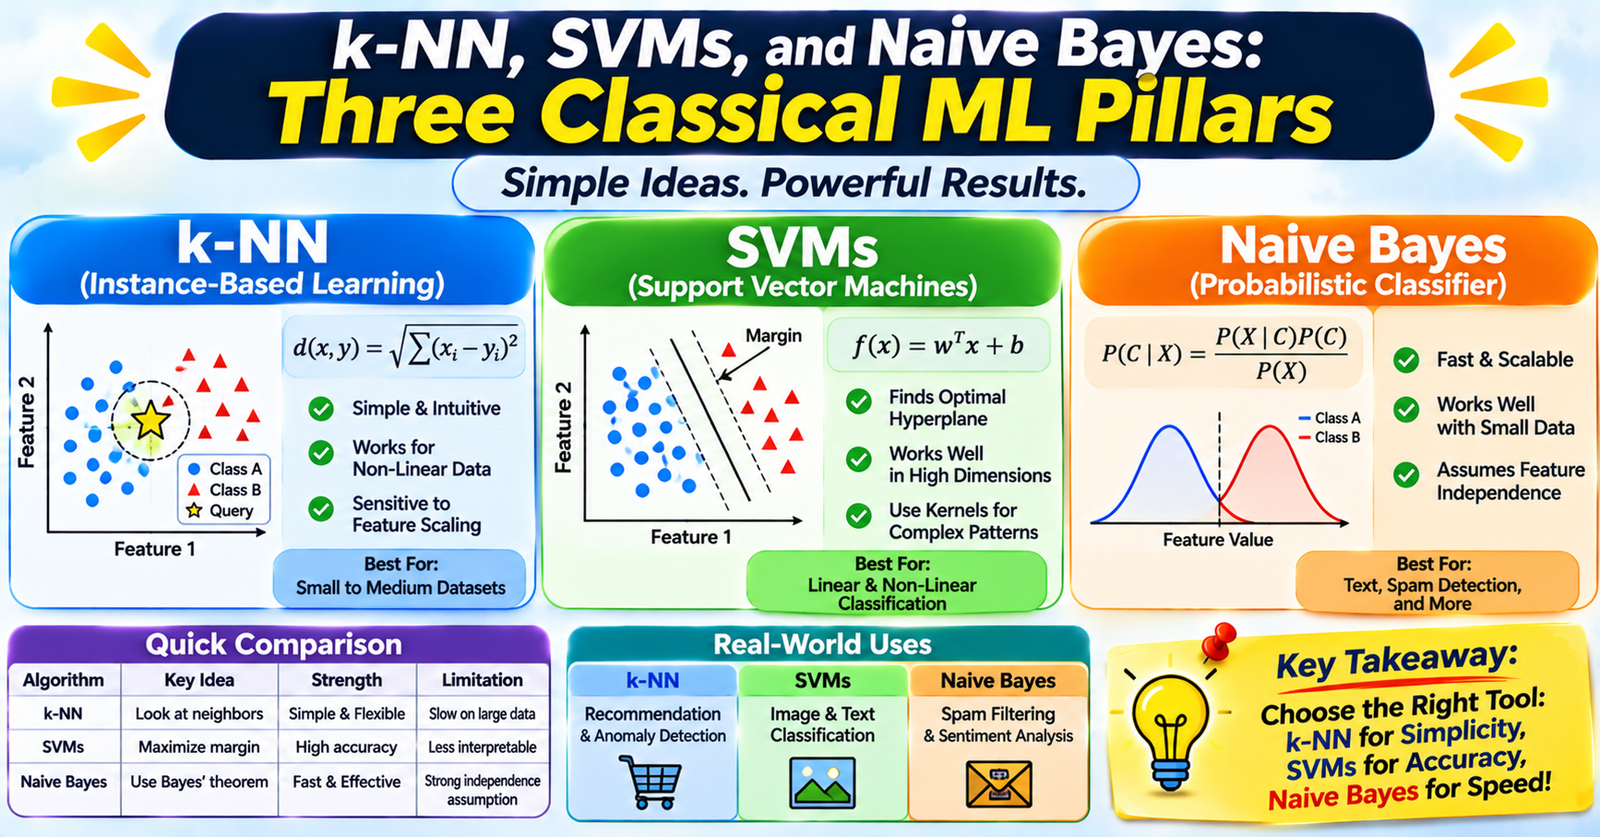
Kulbhushan PukaleCompare three foundational algorithms: k-NN, Support Vector Machines with the kernel trick, and Naive Bayes. Learn their mechanics, mathemat…
Kulbhushan Pukale